Wednesday, February 13, 2013

Post a file to a web page as part of a Maven build process

In a previous post Rest Invocation with Maven I've seen how to invoke a REST service from a Maven Pom file, using the Maven Groovy plugin.

In this post I will show how to upload a file to a webpage, still using some Groovy code.

We will do this in 2 different ways: using plain Apache Http Client and using Rest-assured, the library already described here in this previous post, Rest Assured or Rest-very-Easy

Apache Http Client

Groovy Script
import org.apache.http.impl.client.DefaultHttpClient
import org.apache.http.client.methods.HttpPost
import org.apache.http.entity.mime.MultipartEntity
import org.apache.http.entity.mime.content.FileBody
import org.apache.http.auth.AuthScope
import org.apache.http.auth.UsernamePasswordCredentials

def name = "${input_file}"
log.info( "Archive file: $name" )

def f = new File(name)

// The execution:
DefaultHttpClient httpclient = new DefaultHttpClient()
httpclient.getCredentialsProvider().setCredentials(
     new AuthScope(AuthScope.ANY_HOST, AuthScope.ANY_PORT), 
     new UsernamePasswordCredentials( "${username}", 
          "${password}" )
)

def post = new HttpPost("${form_endpoint}")
def entity = new MultipartEntity()
def fileBody = new FileBody(f)
entity.addPart("file", fileBody)
post.setEntity(entity)

def response = httpclient.execute(post)
def status = response.getStatusLine()
if( !(status ==~ /.*OK.*/) )
     fail("Unable to deploy. Return status code: $status" )
else
     log.info("Deployment Successful: Result status code $status")
Maven configuration
    
      deploy
      
        
          org.apache.httpcomponents
          httpmime
          4.2.1
        
        
          org.apache.httpcomponents
          httpcore
          4.2.1
        
        
          org.apache.httpcomponents
          httpclient
          4.2.1


            org.codehaus.groovy.maven
            gmaven-plugin
            1.0
            
              
                initialize
                
                  execute


Rest-assured

The solution based on HttpClient works fine but it's a little clumsy. We have already agreed that having a script embedded in a pom.xml file is handy but not as clean as writing a full featured Maven Plugin. But even without a complete Maven Plugin we can improve the readability of the script thanks to Rest-assured and the fluent style that allows us to write a much cleared script.

And at the same time we can reduce the number of the direct dependencies in our pom.xml, since we are delegating the rest-assured itself to declare what it needs, that by the way, is again Apache Http Client, since Rest-assured is based on it.

Notice that my script distinguish between .zip and non zip input files, but this distinction it's only dued to the fact that my endpoint was "confused" when I was passing an .zip file without specifying any mimetype. The default mimetype for rest-assured, when you use an overloaded version of .multipart() is application/octet-stream

Groovy Script
import static com.jayway.restassured.RestAssured.*;

def name = "${input_file}"

log.info("Uploading Archive file: $name")

//we have to determine the mimetype to correctly support both zip and xml

def mimeType = name.endsWith("zip") ? "application/zip" : "application/xml"

def f = new File(name)

def response =  with()
   .auth().basic("${username}", "${password}")
   .multiPart("file", f, mimeType)
   .post("${form_endpoint")

def status = response.getStatusLine()
if( !(status ==~ /.*OK.*/) )
     fail("Unable to deploy. Return status code: $status" )
else
     log.info("Deployment Successful: Result status code $status")
Maven configuration
    
      deploy
      
        
          com.jayway.restassured
          rest-assured
          1.4


            org.codehaus.groovy.maven
            gmaven-plugin
            1.0
            
              
                initialize
                
                  execute


Saturday, January 26, 2013

Does Google know who I am? (considering that I have already told him...)

Today I have sent an email to give my opinion about a service and to ask the service provider to consider an improvement.

When I was just about to send it I wondered if the receiver could have been able, if interested in what I have written, to do a lookup up of my mail address and find the pages that represent me better since the address is the one I use in formal communication.

As pages that represent me I mean stuff like my Facebook, Google+, LinkedIn pages, in my case.

And since my email was in the form of "NAME.SURNAME@gmail.com" , a typical standard if you are lucky enough to find it available when you create an email account with a specific provider, I was expecting it to work properly.

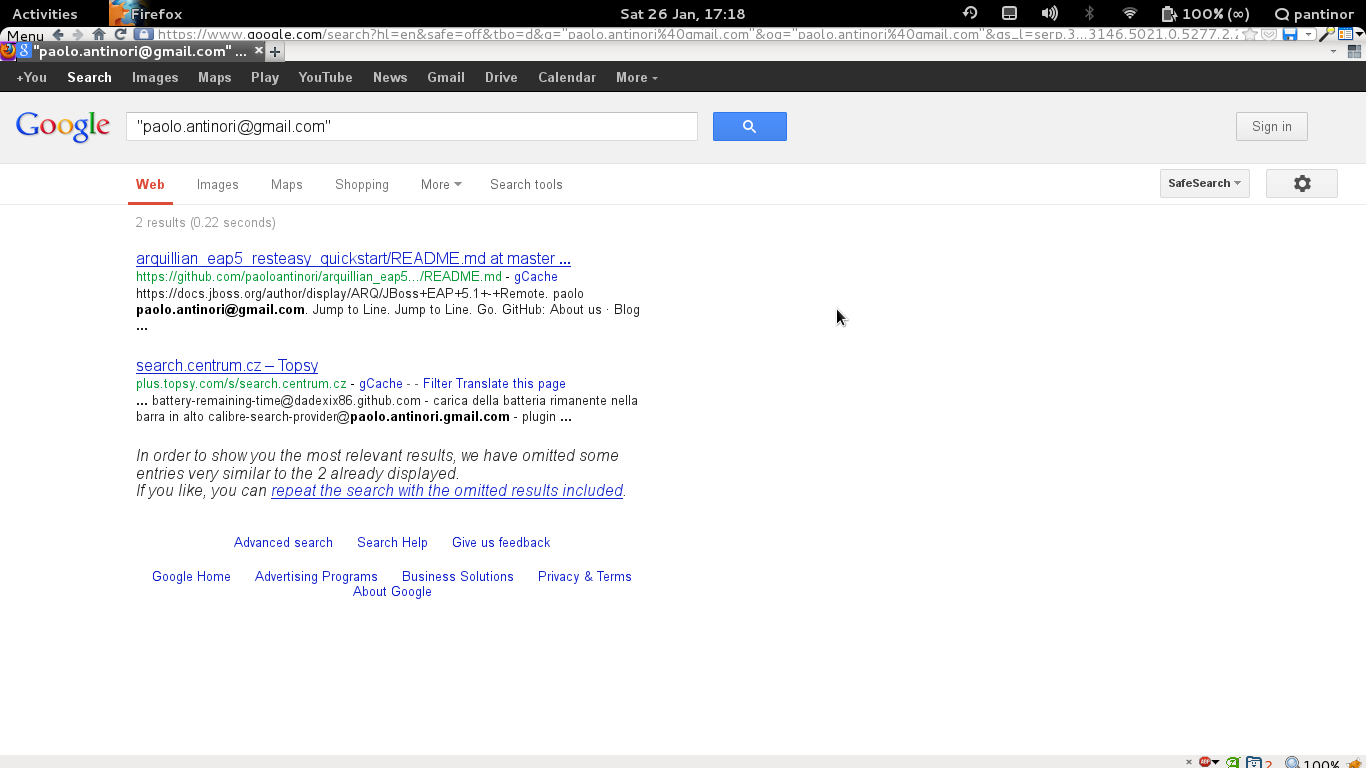
So I performed a test and I have browsed for my official email address in Google search, and to try limit as much as possible, all the tracking informations that my browser could send or remember, I performed my test with an instance of Firefox in Private Mode.

And the result turned to be interesting:

Google identified me correctly... for the first 4 results:

  1. It finds one of my projects on GitHub
  2. It finds my national LinkedIn page
  3. It finds me on LinkedIn.com
  4. It finds my Google+ Page

But it screws it completely for the rest of the first result page links:

For what I have seen from those links, yes, I can say that both my name and my surname, taken independetly are present in the results, but not only I have nothing to do with those pages, but my original query, my NAME.SURNAME@gmail.com email is not there at all and they are not even listing my omonimous.
The pages are not even including the NAME.SURNAME string, that I could expect it may exists as the username chosen by any of my omonimous that could have open an account with providers other than Gmail.

Instead no, the logic that I can guess is that the Google algorithm has not identified my query as an email address and looked just for that.
This behaviour is not completely surprising, since I can expect that the "Did you mean?" functionality could be based on some soundex algorithm or eventually on other statistics and metrics, but the suggested pages are not containing any evident variation of my email address.

It seems to me that email addresses are searched just like any other query on Google and no particular optimization is applied to them. This is definitely surprising, considering the many optimizations or even easter eggs that we can find in the engine:

Try to search for "Apple stock", "1 eur in dollar" or pay attention to the suggested correction when trying to search for "recursion".

I am a software engineer but not an expert in search engines at all, so I do not know if the problem that I am describing is crazy complex or not, but from a user point of view, I do believe that a very common use case is not correctly managed by the search engine.

I know that Search Engine Optimization is a discipline on its own, but my use case is much simpler I think.

From a smart search engine I would expect that if search for an email, the engine would be able to automatically try to look for just the sequence of characters that I have put in the search bar.
Eventually I'd like to receive some suggestion for eventual typos if the system does not find results. I could also accepts suggestion based on similar words, but still in the context of email addresses not just in the the body of other pages.

From a smarter search engine I would expect it to guess that a TOKEN1.TOKEN2 would lead the engine to at least give priority to the option that TOKEN1 could be my name and TOKEN2 could be my surname, and eventually enforce its opinion based of some statistic that could prove that TOKEN1 is indeed a common first name.

I'm saying it again. I really have no clue how doable this idea is, but I do believe that it should not be much harder than now when parts of my search results are correct and others are instead very unrelated to search.

Other interesting considerations based only on my single test:

  • Google finds a page with my full email on Github, because it was on a README text file that I have uploaded there, but it's not suggesting my profile page that still shows publicly my email address.
  • Google+, that also has my official mail public, it's only fourth
  • the ninth result, that is a YouTube page, finds a post of one omonimous of mine.
  • when I searched Google passing my email enclosed by quotes, I receive only 2 results back: the same GitHub page and a scam page.

Java - Handmade Classloader Isolation

In a recent project we had a typical libraries conflict problem.

One component that we could control wanted a specific version of an Apache Commons library, while another component was expecting a different one.

Due to external constraints we could not specify any class loading isolation at the Container level. It wasn't an option for us.

What we decided to do instead has been to use the two different classes definition at the same time.

To obtain this we had to let one class be loaded by the current thread class loader and to load manually the second one; in this way the two classes still have the same fully qualified name.

The only restriction to this approach is the we had to interact with the manually loaded class only via reflection, since the current context, that is using a different class loader, has a different definition of a class and we would be able to cast or assign a instance of the class loaded with a classloader to a variable defined in the context of the other.

Our implementation is in effect a Classloader itself:

DirectoryBasedParentLastURLClassLoader extends ClassLoader

The characteristic of this Classloader is that we are passing it a file system folder path:

public DirectoryBasedParentLastURLClassLoader(String jarDir)

Our implementation scans the filesystem path to produce URLs and uses this information to pass them to a wrapped instance of a URLClassLoader that we are encapsulating with our CustomClassloader:

public DirectoryBasedParentLastURLClassLoader(String jarDir) {
    super(Thread.currentThread().getContextClassLoader());

    // search for JAR files in the given directory
    FileFilter jarFilter = new FileFilter() {
        public boolean accept(File pathname) {
            return pathname.getName().endsWith(".jar");
        }
    };

    // create URL for each JAR file found
    File[] jarFiles = new File(jarDir).listFiles(jarFilter);
    URL[] urls;

    if (null != jarFiles) {
        urls = new URL[jarFiles.length];

        for (int i = 0; i < jarFiles.length; i++) {
            try {
                urls[i] = jarFiles[i].toURI().toURL();
            } catch (MalformedURLException e) {
                throw new RuntimeException(
                        "Could not get URL for JAR file: " + jarFiles[i], e);
            }
        }

    } else {
        // no JAR files found
        urls = new URL[0];
    }

    childClassLoader = new ChildURLClassLoader(urls, this.getParent());
}

With this setup we can override the behaviour of the main classloading functionality, giving priority to the loading from our folder and falling back to the parent classloader only if we could find the requested class:

@Override
protected synchronized Class loadClass(String name, boolean resolve)
        throws ClassNotFoundException {
    try {
        // first try to find a class inside the child classloader
        return childClassLoader.findClass(name);
    } catch (ClassNotFoundException e) {
        // didn't find it, try the parent
        return super.loadClass(name, resolve);
    }
}

With our CustomClassloader in place we can use it in this way:

//instantiate our custom classloader
DirectoryBasedParentLastURLClassLoader classLoader = new DirectoryBasedParentLastURLClassLoader(
        ClassLoaderTest.JARS_DIR    );
//manually load a specific class
Class classManuallyLoaded = classLoader
        .loadClass("paolo.test.custom_classloader.support.MyBean");
//request a class via reflection
Object myBeanInstanceFromReflection = classManuallyLoaded.newInstance();
//keep using the class via reflection
Method methodToString = classManuallyLoaded.getMethod("toString");
assertEquals("v1", methodToString.invoke(myBeanInstanceFromReflection));

This idea for this post and part of its code come from this interesting discussion on Stackoverflow

A fully working Maven project is available on GitHub with a bunch of unit tests to verify the right behaviour.

Tuesday, January 15, 2013

Java: Rest-assured (or Rest-Very-Easy)


Recently I had to write some Java code to consume REST services over HTTP.

I've decided to use the Client libraries of RestEasy, the framework I use most of the time to expose REST services in Java, since it also implements the official JAX-RS specification.

I am very satisfied with the annotation driven approach that the specification defines and it makes exposing REST services a very pleasant task.

But unluckily I cannot say that I like the client API the same way.

If you are lucky enough to be able to build a proxy client based on the interface implemented by the service, well, that's not bad:

import org.jboss.resteasy.client.ProxyFactory;
...
// this initialization only needs to be done once per VM
RegisterBuiltin.register(ResteasyProviderFactory.getInstance());


SimpleClient client = ProxyFactory.create(MyRestServiceInterface.class, "http://localhost:8081");
client.myBusinessMethod("hello world");
Having a Proxy client similar to a  JAX-WS one is good, I do agree. But most of the time, when we are consuming REST web service we do not have a Java interface to import.
All those Twitter, Google or whatever public rest services available out there are just HTTP endpoints.

The way to go with RestEasy in these cases is to rely on the RestEasy Manual ClientRequest API:

ClientRequest request = new ClientRequest("http://localhost:8080/some/path");
request.header("custom-header", "value");

// We're posting XML and a JAXB object
request.body("application/xml", someJaxb);

// we're expecting a String back
ClientResponse<String> response = request.post(String.class);

if (response.getStatus() == 200) // OK!
{
   String str = response.getEntity();
}
That is in my opinion a very verbose way to fetch what is most of the time, just a bunch of strings from the web. And it gets even worse if you need to include Authentication informations:

// Configure HttpClient to authenticate preemptively
// by prepopulating the authentication data cache.
 
// 1. Create AuthCache instance
AuthCache authCache = new BasicAuthCache();
 
// 2. Generate BASIC scheme object and add it to the local auth cache
BasicScheme basicAuth = new BasicScheme();
authCache.put("com.bluemonkeydiamond.sippycups", basicAuth);
 
// 3. Add AuthCache to the execution context
BasicHttpContext localContext = new BasicHttpContext();
localContext.setAttribute(ClientContext.AUTH_CACHE, authCache);
 
// 4. Create client executor and proxy
httpClient = new DefaultHttpClient();
ApacheHttpClient4Executor executor = new ApacheHttpClient4Executor(httpClient, localContext);
client = ProxyFactory.create(BookStoreService.class, url, executor);

I have found that Rest-assured  provide a much nicer API to write client invocations.
Officially the aim of the project is to create a testing and validating framework; and most of the tutorials out there are covering those aspects, like the recent Heiko Rupp's one: http://pilhuhn.blogspot.nl/2013/01/testing-rest-apis-with-rest-assured.html

I suggest  yout, instead, to use it as a development tool to experiment and write REST invocation very rapidly.

What is important to know about rest-assured:

  •  it implements a Domain Specific Language thanks to fluid API
  •  it is a single Maven dependency
  •  it almost completely expose a shared style for both xml and json response objects
  •  it relies on Apache Commons Client

So, I'll show you a bunch of real world use cases and I will leave you with some good link if you want to know more.

As most of the DSL on Java, it works better if you import statically the most
important objects:
import static   com.jayway.restassured.RestAssured.*;
import static   com.jayway.restassured.matcher.RestAssuredMatchers.*;
Base usage:
get("http://api.twitter.com/1/users/show.xml").asString();

That returns:

  Sorry, that page does not exist

Uh oh, some error. Yeah, we need to pass some parameter:
with()
    .parameter("screen_name", "resteasy")
.get("http://api.twitter.com/1/users/show.xml").asString();

That returns:

  27016395
  Resteasy
  resteasy
  
  http://a0.twimg.com/sticky/default_profile_images/default_profile_0_normal.png
  https://si0.twimg.com/sticky/default_profile_images/default_profile_0_normal.png
  
  jboss.org/resteasy

JBoss/Red Hat REST project
  false
  244
  C0DEED
  333333
  0084B4
  DDEEF6
  C0DEED
  1
  Fri Mar 27 14:39:52 +0000 2009
  0
  
  
  http://a0.twimg.com/images/themes/theme1/bg.png
  https://si0.twimg.com/images/themes/theme1/bg.png
  false
  true
  false
  false
  8
  en
  false
  false
  21
  true
  true
...

Much better! Now, let's say that we want only a token of this big String XML:
with()
    .parameter("screen_name", "resteasy")
.get("http://api.twitter.com/1/users/show.xml")
    .path("user.profile_image_url")

And here's our output:
http://a0.twimg.com/sticky/default_profile_images/default_profile_0_normal.png

What if it was a JSON response?
with()
    .parameter("screen_name", "resteasy")
.get("http://api.twitter.com/1/users/show.json")

And here's our output:
{"id":27016395,"id_str":"27016395","name":"Resteasy","screen_name":"resteasy","location":"","url":null,"description":"jboss.org\/resteasy\n\nJBoss\/Red Hat REST project","protected":false,"followers_count":244,"friends_count":1,"listed_count":21,"created_at":"Fri Mar 27 14:39:52 +0000 2009","favourites_count":0,"utc_offset":null,"time_zone":null,"geo_enabled":false,"verified":false,"statuses_count":8,"lang":"en","status":{"created_at":"Tue Mar 23 14:48:51 +0000 2010","id":10928528312,"id_str":"10928528312","text":"Doing free webinar tomorrow on REST, JAX-RS, RESTEasy, and REST-*.  Only 40 min, so its brief.  http:\/\/tinyurl.com\/yz6xwek","source":"web","truncated":false,"in_reply_to_status_id":null,"in_reply_to_status_id_str":null,"in_reply_to_user_id":null,"in_reply_to_user_id_str":null,"in_reply_to_screen_name":null,"geo":null,"coordinates":null,"place":null,"contributors":null,"retweet_count":0,"favorited":false,"retweeted":false},"contributors_enabled":false,"is_translator":false,"profile_background_color":"C0DEED","profile_background_image_url":"http:\/\/a0.twimg.com\/images\/themes\/theme1\/bg.png","profile_background_image_url_https":"https:\/\/si0.twimg.com\/images\/themes\/theme1\/bg.png","profile_background_tile":false,"profile_image_url":"http:\/\/a0.twimg.com\/sticky\/default_profile_images\/default_profile_0_normal.png","profile_image_url_https":"https:\/\/si0.twimg.com\/sticky\/default_profile_images\/default_profile_0_normal.png","profile_link_color":"0084B4","profile_sidebar_border_color":"C0DEED","profile_sidebar_fill_color":"DDEEF6","profile_text_color":"333333","profile_use_background_image":true,"default_profile":true,"default_profile_image":true,"following":null,"follow_request_sent":null,"notifications":null}

And the same interface undestands JSON object navigation. Note that the navigation expression does not include "user" since it was not there in the full json response:
with()
    .parameter("screen_name", "resteasy")
.get("http://api.twitter.com/1/users/show.json")
    .path("profile_image_url")

And here's our output:
http://a0.twimg.com/sticky/default_profile_images/default_profile_0_normal.png

Now an example of Path Parameters:
with()
    .parameter("key", "HomoSapiens")
.get("http://eol.org/api/search/{key}").asString()

Information about the http request:
get("http://api.twitter.com/1/users/show.xml").statusCode();
get("http://api.twitter.com/1/users/show.xml").statusLine();

An example of Basic Authentication:
with()
  .auth().basic("paolo", "xxxx")
.get("http://localhost:8080/b/secured/hello")
  .statusLine()

An example of Multipart Form Upload
with()
    .multiPart("file", "test.txt", fileContent.getBytes())
.post("/upload")

Maven dependency:

 com.jayway.restassured
 rest-assured
 1.4
 test


And a Groovy snippet that can be pasted and executed directly in groovyConsole thanks to Grapes fetches the dependencies and add them automatically to the classpath, that shows you JAXB support:
@Grapes([  
    @Grab("com.jayway.restassured:rest-assured:1.7.2")
])
import static   com.jayway.restassured.RestAssured.*
import static   com.jayway.restassured.matcher.RestAssuredMatchers.*
import  javax.xml.bind.annotation.*


@XmlRootElement(name = "user")
@XmlAccessorType( XmlAccessType.FIELD )
    class TwitterUser {
        String id;
        String name;
        String description;
        String location;

        @Override
        String toString() {
            return "Id: $id, Name: $name, Description: $description, Location: $location"
        }

    }

println with().parameter("screen_name", "resteasy").get("http://api.twitter.com/1/users/show.xml").as(TwitterUser.class)

//


This is just a brief list of the features of the library, just you an idea of how easy it is to work with it. For a further examples I suggest you to read the official pages here:

https://code.google.com/p/rest-assured/wiki/Usage

Or another good tutorial here with a sample application to play with:

http://www.hascode.com/2011/10/testing-restful-web-services-made-easy-using-the-rest-assured-framework

Thursday, December 20, 2012

Maven - Install missing offline dependencies automatically

Sometime it happens that we need to share with someone else part of a complex Java project based on Maven.
The project is probably composed of various modules, with their dependency relationships, but the different modules are also logically separated. So it make completely sense that we'd like to share only on those submodules.

To do that we have to modify the pom.xml and remove the <parent> section and probably also specify properties and dependencies version that are often defined in the super pom.
But with the help of Eclipse and its "Effective POM" view it's not that hard.

The real problem is that all those actions are not enough to have a portable project.
What is missing is the list of dependency defined in the submodules that we do not want to share as source code and that won't be available to be downloaded from Maven public repositories.

Since those artifacts are required to build the project, what we can do is to manually install them from the command line with the typical:

mvn install:install-file 
 -Dfile=my_module.jar 
 -DgroupId=my.private.project 
 -DartifactId=my_module 
 -Dversion=1.0.0 
 -Dpackaging=jar
It works but it contrasts with the idea that our Maven build should be able to do all is required to build our project.

I was looking for an alternative solution and I have found it in this post on Stackoverflow: http://stackoverflow.com/questions/1355548/maven-including-jar-not-found-in-public-repository

 Let me describe it and also offer a ready git repo for a rapid testing of it.

https://github.com/paoloantinori/maven_automated_artifacts_installation

The main idea is to use the exec-maven-plugin to automatically install the dependency for us, replicating the manual activity.
In this way we can script all the manual activities that we needed. To better distinguish between what are the external libraries and our project I suggest a multimodule project:

Parent
|
+---Dependency Project
|
+---Our Interesting Project
Nothing interesting in the parent pom.xml:

  pom
  Sample :: Multimodule
  
  
    main_project
    dependencies_project
  

Let's have a look at the Main Project pom.xml:


      com.example.giallone
      dependencies
      1.0.0


      com.example.giallone
      dep1
      1.0.0
    
    
      com.example.giallone
      dep2
      1.0.0
    
  
As you can see we are defining 2 different things:

Under "real dependencies" you see references to artifacts that the project needs but are not available in Maven Public Repositories.

While instead the first dependency is to trigger the installation of those missing jars, action performed by the other module of this multimodule project.

 If you try now to build only this module it will fail with the following output , since those missing dependencies have not been installed yet:


pantinor@pantinor main_project$ mvn clean install
/usr/lib/jvm/java
[INFO] Scanning for projects...
[INFO]                                                                         
[INFO] ------------------------------------------------------------------------
[INFO] Building Sample :: Main Project 1.0.0
[INFO] ------------------------------------------------------------------------
Downloading: http://repo.maven.apache.org/maven2/com/example/giallone/dependencies/1.0.0/dependencies-1.0.0.pom
[WARNING] The POM for com.example.giallone:dependencies:jar:1.0.0 is missing, no dependency information available
[WARNING] The POM for com.example.giallone:dep1:jar:1.0.0 is missing, no dependency information available
[WARNING] The POM for com.example.giallone:dep2:jar:1.0.0 is missing, no dependency information available
Downloading: http://repo.maven.apache.org/maven2/com/example/giallone/dependencies/1.0.0/dependencies-1.0.0.jar
[INFO] ------------------------------------------------------------------------
[INFO] BUILD FAILURE
[INFO] ------------------------------------------------------------------------
[INFO] Total time: 1.166s
[INFO] Finished at: Thu Dec 20 13:02:20 GMT 2012
[INFO] Final Memory: 5M/148M
[INFO] ------------------------------------------------------------------------
[ERROR] Failed to execute goal on project rules: Could not resolve dependencies for project com.example.giallone:rules:jar:1.0.0: The following artifacts could not be resolved: com.example.giallone:dependencies:jar:1.0.0, com.example.giallone:dep1:jar:1.0.0, com.example.giallone:dep2:jar:1.0.0: Could not find artifact com.example.giallone:dependencies:jar:1.0.0 in central (http://repo.maven.apache.org/maven2) -> [Help 1]
[ERROR] 
[ERROR] To see the full stack trace of the errors, re-run Maven with the -e switch.
[ERROR] Re-run Maven using the -X switch to enable full debug logging.
[ERROR] 
[ERROR] For more information about the errors and possible solutions, please read the following articles:
[ERROR] [Help 1] http://cwiki.apache.org/confluence/display/MAVEN/DependencyResolutionException


Let's now have a look at the other module, dependencies_project:


        org.codehaus.mojo
        exec-maven-plugin
        1.2.1
        false
        
          
            install-in-repo-dep1
            validate
            
              exec
            
            
              mvn
              
                install:install-file
                -Dfile=${basedir}/lib/dep1.jar
                -DgroupId=com.example.giallone
                -DartifactId=dep1
                -Dversion=1.0.0
                -Dpackaging=jar


            install-in-repo-dep2
            validate
            
              exec
            
            
              mvn
              
                install:install-file
                -Dfile=${basedir}/lib/dep2.jar
                -DgroupId=com.example.giallone
                -DartifactId=dep2
                -Dversion=1.0.0
                -Dpackaging=jar


What we are doing here is to use exec-maven-plugin to install for us the missing dependencies in the local repo.
Those are the dependencies that prevent our main project to build successfully.

Having configured our main project to be dependent on this one, if we now build our project at the multimodule level, we will be able to trigger the 2 module in the right order:

[INFO] Reactor Build Order:
[INFO] 
[INFO] Sample :: Multimodule
[INFO] Sample :: Dependencies
[INFO] Sample :: Main Project


And when Multimodule Project is built, all the external dependencies are already installed in the previous step, allowing us to see a successful build! 

pantinor@pantinor install_artifacts_sample$ mvn clean install
/usr/lib/jvm/java
[INFO] Scanning for projects...
[INFO] ------------------------------------------------------------------------
[INFO] Reactor Build Order:
[INFO] 
[INFO] Sample :: Multimodule
[INFO] Sample :: Dependencies
[INFO] Sample :: Main Project
[INFO]                                                                         
[INFO] ------------------------------------------------------------------------
[INFO] Building Sample :: Multimodule 1.0.0
[INFO] ------------------------------------------------------------------------
[INFO] 
[INFO] --- maven-clean-plugin:2.4.1:clean (default-clean) @ common ---
[INFO] 
[INFO] --- maven-install-plugin:2.3.1:install (default-install) @ common ---
[INFO] Installing /data/repositories/github/install_artifacts_sample/pom.xml to /home/pantinor/.m2/repository/com/example/giallone/common/1.0.0/common-1.0.0.pom
[INFO]                                                                         
[INFO] ------------------------------------------------------------------------
[INFO] Building Sample :: Dependencies 1.0.0
[INFO] ------------------------------------------------------------------------
[INFO] 
[INFO] --- maven-clean-plugin:2.4.1:clean (default-clean) @ dependencies ---
[INFO] Deleting /data/repositories/github/install_artifacts_sample/dependencies_project/target
[INFO] 
[INFO] --- exec-maven-plugin:1.2.1:exec (install-in-repo-dep1) @ dependencies ---
/usr/lib/jvm/java
[INFO] Scanning for projects...
[INFO]                                                                         
[INFO] ------------------------------------------------------------------------
[INFO] Building Sample :: Dependencies 1.0.0
[INFO] ------------------------------------------------------------------------
[INFO] 
[INFO] --- maven-install-plugin:2.3.1:install-file (default-cli) @ dependencies ---
[INFO] Installing /data/repositories/github/install_artifacts_sample/dependencies_project/lib/dep1.jar to /home/pantinor/.m2/repository/com/example/giallone/dep1/1.0.0/dep1-1.0.0.jar
[INFO] Installing /tmp/mvninstall204045843544074291.pom to /home/pantinor/.m2/repository/com/example/giallone/dep1/1.0.0/dep1-1.0.0.pom
[INFO] ------------------------------------------------------------------------
[INFO] BUILD SUCCESS
[INFO] ------------------------------------------------------------------------
[INFO] Total time: 0.782s
[INFO] Finished at: Thu Dec 20 13:06:58 GMT 2012
[INFO] Final Memory: 4M/117M
[INFO] ------------------------------------------------------------------------
[INFO] 
[INFO] --- exec-maven-plugin:1.2.1:exec (install-in-repo-dep2) @ dependencies ---
/usr/lib/jvm/java
[INFO] Scanning for projects...
[INFO]                                                                         
[INFO] ------------------------------------------------------------------------
[INFO] Building Sample :: Dependencies 1.0.0
[INFO] ------------------------------------------------------------------------
[INFO] 
[INFO] --- maven-install-plugin:2.3.1:install-file (default-cli) @ dependencies ---
[INFO] Installing /data/repositories/github/install_artifacts_sample/dependencies_project/lib/dep2.jar to /home/pantinor/.m2/repository/com/example/giallone/dep2/1.0.0/dep2-1.0.0.jar
[INFO] Installing /tmp/mvninstall3544830050220263281.pom to /home/pantinor/.m2/repository/com/example/giallone/dep2/1.0.0/dep2-1.0.0.pom
[INFO] ------------------------------------------------------------------------
[INFO] BUILD SUCCESS
[INFO] ------------------------------------------------------------------------
[INFO] Total time: 1.116s
[INFO] Finished at: Thu Dec 20 13:07:01 GMT 2012
[INFO] Final Memory: 5M/148M
[INFO] ------------------------------------------------------------------------
[INFO] 
[INFO] --- maven-resources-plugin:2.5:resources (default-resources) @ dependencies ---
[debug] execute contextualize
[WARNING] Using platform encoding (UTF-8 actually) to copy filtered resources, i.e. build is platform dependent!
[INFO] skip non existing resourceDirectory /data/repositories/github/install_artifacts_sample/dependencies_project/src/main/resources
[INFO] 
[INFO] --- maven-compiler-plugin:2.3.2:compile (default-compile) @ dependencies ---
[INFO] No sources to compile
[INFO] 
[INFO] --- maven-resources-plugin:2.5:testResources (default-testResources) @ dependencies ---
[debug] execute contextualize
[WARNING] Using platform encoding (UTF-8 actually) to copy filtered resources, i.e. build is platform dependent!
[INFO] skip non existing resourceDirectory /data/repositories/github/install_artifacts_sample/dependencies_project/src/test/resources
[INFO] 
[INFO] --- maven-compiler-plugin:2.3.2:testCompile (default-testCompile) @ dependencies ---
[INFO] No sources to compile
[INFO] 
[INFO] --- maven-surefire-plugin:2.10:test (default-test) @ dependencies ---
[INFO] No tests to run.
[INFO] Surefire report directory: /data/repositories/github/install_artifacts_sample/dependencies_project/target/surefire-reports

-------------------------------------------------------
 T E S T S
-------------------------------------------------------

Results :

Tests run: 0, Failures: 0, Errors: 0, Skipped: 0

[INFO] 
[INFO] --- maven-jar-plugin:2.3.2:jar (default-jar) @ dependencies ---
[WARNING] JAR will be empty - no content was marked for inclusion!
[INFO] Building jar: /data/repositories/github/install_artifacts_sample/dependencies_project/target/dependencies-1.0.0.jar
[INFO] 
[INFO] --- maven-install-plugin:2.3.1:install (default-install) @ dependencies ---
[INFO] Installing /data/repositories/github/install_artifacts_sample/dependencies_project/target/dependencies-1.0.0.jar to /home/pantinor/.m2/repository/com/example/giallone/dependencies/1.0.0/dependencies-1.0.0.jar
[INFO] Installing /data/repositories/github/install_artifacts_sample/dependencies_project/pom.xml to /home/pantinor/.m2/repository/com/example/giallone/dependencies/1.0.0/dependencies-1.0.0.pom
[INFO]                                                                         
[INFO] ------------------------------------------------------------------------
[INFO] Building Sample :: Main Project 1.0.0
[INFO] ------------------------------------------------------------------------
[INFO] 
[INFO] --- maven-clean-plugin:2.4.1:clean (default-clean) @ rules ---
[INFO] Deleting /data/repositories/github/install_artifacts_sample/main_project/target
[INFO] 
[INFO] --- maven-resources-plugin:2.5:resources (default-resources) @ rules ---
[debug] execute contextualize
[WARNING] Using platform encoding (UTF-8 actually) to copy filtered resources, i.e. build is platform dependent!
[INFO] skip non existing resourceDirectory /data/repositories/github/install_artifacts_sample/main_project/src/main/resources
[INFO] 
[INFO] --- maven-compiler-plugin:2.3.2:compile (default-compile) @ rules ---
[INFO] No sources to compile
[INFO] 
[INFO] --- maven-resources-plugin:2.5:testResources (default-testResources) @ rules ---
[debug] execute contextualize
[WARNING] Using platform encoding (UTF-8 actually) to copy filtered resources, i.e. build is platform dependent!
[INFO] skip non existing resourceDirectory /data/repositories/github/install_artifacts_sample/main_project/src/test/resources
[INFO] 
[INFO] --- maven-compiler-plugin:2.3.2:testCompile (default-testCompile) @ rules ---
[INFO] No sources to compile
[INFO] 
[INFO] --- maven-surefire-plugin:2.10:test (default-test) @ rules ---
[INFO] No tests to run.
[INFO] Surefire report directory: /data/repositories/github/install_artifacts_sample/main_project/target/surefire-reports

-------------------------------------------------------
 T E S T S
-------------------------------------------------------

Results :

Tests run: 0, Failures: 0, Errors: 0, Skipped: 0

[INFO] 
[INFO] --- maven-jar-plugin:2.3.2:jar (default-jar) @ rules ---
[WARNING] JAR will be empty - no content was marked for inclusion!
[INFO] Building jar: /data/repositories/github/install_artifacts_sample/main_project/target/rules-1.0.0.jar
[INFO] 
[INFO] --- maven-install-plugin:2.3.1:install (default-install) @ rules ---
[INFO] Installing /data/repositories/github/install_artifacts_sample/main_project/target/rules-1.0.0.jar to /home/pantinor/.m2/repository/com/example/giallone/rules/1.0.0/rules-1.0.0.jar
[INFO] Installing /data/repositories/github/install_artifacts_sample/main_project/pom.xml to /home/pantinor/.m2/repository/com/example/giallone/rules/1.0.0/rules-1.0.0.pom
[INFO] ------------------------------------------------------------------------
[INFO] Reactor Summary:
[INFO] 
[INFO] Sample :: Multimodule ............................. SUCCESS [0.545s]
[INFO] Sample :: Dependencies ............................ SUCCESS [6.800s]
[INFO] Sample :: Main Project ............................ SUCCESS [0.344s]
[INFO] ------------------------------------------------------------------------
[INFO] BUILD SUCCESS
[INFO] ------------------------------------------------------------------------
[INFO] Total time: 7.816s
[INFO] Finished at: Thu Dec 20 13:07:03 GMT 2012
[INFO] Final Memory: 7M/117M
[INFO] ------------------------------------------------------------------------

Sunday, December 16, 2012

git - let's make errors ( and learn how to revert them )

It's not a secret that git is not a very easy tool to use.

I am able to use it more or less; but I always feel a little scared and confused about what's happening.
I feel that I want more informations.
I have followed some tutorial and read distractedly some book but, with too much information I always end up with just the feeling that I could do what I want to do. But I do not know how to do it.

I want to fix this situation so I have started to investigate more and I am trying to stick some key concept in my head, hoping to never forget them.

Let me start giving the credits for my source:

http://osteele.com/posts/2008/05/my-git-workflow
and
http://longair.net/blog/2009/04/16/git-fetch-and-merge/

I have found those articles interesting and helpful, the first in particular, but they are saying already too many things for the simplified model that I need.

Let's assume that you are already a git user.

You have a local repo, a remote one used to pull and push you work. And you also are aware of the existence of branches and you are using them. But still, with this basic knowledge you have the feeling of not being sure about your actions.

I guess that one of the key of this confusion is the role of the staging area. Please, note that in my discussion I am giving my understanding of it, and that I could be wrong. But nevertheless I can build my knowledge on this concept and be able to give my self a rationale behind it that helps me to gain confidence with the tool.

I like to think at the staging area, (that place where your modifications get tracked when you perform a git add operation, as a way to do "lighter commit". What I mean with lighter commit is that, since you are not forced to give a comment upon this action, you have less constraints. And since you are not even saving your action yet, you are clearly encouraged to perform add much more often than commit.

Let's give a scenario for our add use case: the process of adding some new functionality to your codebase; it probably involves the creation of new files and ideas just pop in your mind in an unordered fashion.

To give an example, let's pretend that you are creating 2 files with a reference to each other. Maybe a source code file and it's configuration file. You create the first, and start working on it. When you have finished to work on it you could think to commit it, but since your logical unit of work is not complete until you'll also create the configuration file you have the opportunity to perform the mentioned "lighter commit, i.e. a simple add. After you have finished the work with the configuration file, you have to add it to the index and now you can commit it. Or if you prefer you can do a git commit -a , to obtain the same result.

Since we have given a use case for the staging area, it should become easier to figure it's role in the git workflow. It's the logical place that stays between the current untracked directory and the committed (and safe) repository.

We are calling it a "place" so we can assume that we are interested in interacting with it. The already well known way to put things in it is the command:

git add


and it has 2 companion commands that you will use very often:

git diff


As the name suggests, it lists differences. But which ones? In its form without parameters, it lists differences between your current folder and the staging area.

touch test.txt
echo "text" >> test.txt
git add test.txt
echo "added1" >> test.txt
git diff
  returns this output:  
gittest$ git diff
 
diff --git a/test.txt b/test.txt
index 8e27be7..2db9057 100644
--- a/test.txt
+++ b/test.txt
@@ -1 +1,2 @@
 text
+added1

Ok we are now able to see differences between our working folder and the tracking context. We can obviously track the new modification, with an add command but we want also the opportunity to throw away our modification.

This is obtained with

git checkout .


Git checkout, without parameters (others than "dot", representing the current folder) will throw away the modification to your files and revert the status to the one tracked in the staging area with the previous add commands.

gittest$ git status


# On branch master
# Changes to be committed:
#   (use "git reset HEAD <file>..." to unstage)
#
#    new file:   test.txt
#
# Changes not staged for commit:
#   (use "git add <file>..." to update what will be committed)
#   (use "git checkout -- <file>..." to discard changes in working directory)
#
#    modified:   test.txt
#
 

gittest$ git checkout .


gittest$ git status
# On branch master
# Changes to be committed:
#   (use "git reset HEAD <file>..." to unstage)
#
#    new file:   test.txt
#


We have given a meaning to the staging area. And we can also think about it as the very first "environment" we are facing with, since every command without specific parameters works on staging.

Let's move on. We are now able to add or discard changings to the staging area. We also know how to persistently store the changings, via git commit. What we do not yet know how to do is to discard completely our staging area.

With a parallel with what we just did before, discarding staging is performed with:

git checkout HEAD .


That technically means that we are reverting to a specific commit point, the last one(HEAD).


Before testing this we have to perform a couple of interactions since inconsistent git behaviour doesn't allow us to execute the test right away. The reason is because our file was a "new" file and not a "modified" one. This breaks the symmetry but let me come back on this concept later.


@pantinor gittest$ git status
# On branch master
# Changes to be committed:
#   (use "git reset HEAD <file>..." to unstage)
#
#    new file:   test.txt
#
pantinor@pantinor gittest$ git commit -m "added new file"
[master f331e52] added new file
 1 file changed, 1 insertion(+)
 create mode 100644 test.txt
pantinor@pantinor gittest$ git status
# On branch master
nothing to commit (working directory clean)
pantinor@pantinor gittest$ echo "added" >> test.txt 
pantinor@pantinor gittest$ git status
# On branch master
# Changes not staged for commit:
#   (use "git add <file>..." to update what will be committed)
#   (use "git checkout -- <file>..." to discard changes in working directory)
#
#    modified:   test.txt
#
no changes added to commit (use "git add" and/or "git commit -a")
pantinor@pantinor gittest$ git add test.txt
pantinor@pantinor gittest$ git status
# On branch master
# Changes to be committed:
#   (use "git reset HEAD <file>..." to unstage)
#
#    modified:   test.txt
#
pantinor@pantinor gittest$ git checkout HEAD .
pantinor@pantinor gittest$ git status
# On branch master
nothing to commit (working directory clean)


We have just learnt how to revert to a clean situation.

We are now much less scared of the staging area.

But we are still bad git users. We always forget to branch before starting to modify a working folder as suggested here:

http://nvie.com/posts/a-successful-git-branching-model/

In my case it often goes like this: I have a stable situation, than I start to tweak something. But the tweaking is not linear and after some minutes I have lots of modified files.
Yes, I could stage them all and commit them, but I do not trust myself and I do not want to pollute the master branch. It would have been much better if I was on a dev branch from the beginning of my modifications. What I could do now?

We can create on the fly a branch and switch to it.

pantinor@pantinor gittest$ echo something >> test.txt 
pantinor@pantinor gittest$ git status
# On branch master
# Changes not staged for commit:
#   (use "git add <file>..." to update what will be committed)
#   (use "git checkout -- <file>..." to discard changes in working directory)
#
#    modified:   test.txt
#
no changes added to commit (use "git add" and/or "git commit -a")
pantinor@pantinor gittest$ git checkout -b dev
M    test.txt
Switched to a new branch 'dev'


On this new branch we will still accessing the shared staging area as you can see from my output:

pantinor@pantinor gittest$ git status
# On branch dev
# Changes not staged for commit:
#   (use "git add <file>..." to update what will be committed)
#   (use "git checkout -- <file>..." to discard changes in working directory)
#
#    modified:   test.txt
#
no changes added to commit (use "git add" and/or "git commit -a")


What we want to do now, is to add the working situation to the staging and to commit it, so to be able to flush the shared staging area.

pantinor@pantinor gittest$ git add .
pantinor@pantinor gittest$ git commit -m unstable
[dev 5d597b2] unstable
 1 file changed, 1 insertion(+)
pantinor@pantinor gittest$ git status
# On branch dev
nothing to commit (working directory clean)

pantinor@pantinor gittest$ cat test.txt 
text
something


and then, when we will go back to our master, we can find it free of all our experimental modification, not mature for the master branch:

pantinor@pantinor gittest$ git checkout master
Switched to branch 'master'
pantinor@pantinor gittest$ git status
# On branch master
nothing to commit (working directory clean)
pantinor@pantinor gittest$ echo test.txt 
test.txt


Great. Keeping our commands relatively simple and free of parameters and flag we are able to do all the errors that we are inevitable going to do anyway.

Let's now introduce another pattern to cope with our other typical errors. The situation is similar to the one just described, but a little worse. Again, we haven't branched before starting to play with the code, but this time we have also committed a couple of times before realizing that what we have committed is not as good as we thought. What we want to do this time, is to keep our unstable situation, but we want to move it away( hard reset) from the current branch.

Let's do a couple of commits:

pantinor@pantinor gittest$ git status
# On branch master
nothing to commit (working directory clean)
pantinor@pantinor gittest$ cat test.txt 
text
pantinor@pantinor gittest$ echo "modification1" >> test.txt 
pantinor@pantinor gittest$ git commit -a -m"first commit"
[master 9ad2aa8] first commit
 1 file changed, 1 insertion(+)
pantinor@pantinor gittest$ echo "modification2" >> test.txt 
pantinor@pantinor gittest$ git commit -a -m"second commit"
[master 7005a92] second commit
 1 file changed, 1 insertion(+)
pantinor@pantinor gittest$ cat test.txt 
text
modification1
modification2
pantinor@pantinor gittest$ git log
commit 7005a92a3ceee37255dc7143239d55c7c3467551
Author: Paolo Antinori <pantinor redhat.com="redhat.com">
Date:   Sun Dec 16 21:05:48 2012 +0000

    second commit

commit 9ad2aa8fae1cbd844f34da2701e80d2c6e39320e
Author: Paolo Antinori <pantinor redhat.com="redhat.com">
Date:   Sun Dec 16 21:05:23 2012 +0000

    first commit

commit f331e52f41a862d727869b52e2e42787aa4cb57f
Author: Paolo Antinori <pantinor redhat.com="redhat.com">
Date:   Sun Dec 16 20:20:15 2012 +0000

    added new file

At this point we want to move the last 2 commit to a different branch:

git branch unstable


We created a new branch, but we haven't switched to it.

The just created new branch has obviously everything that was present at the time of its creation, i.e. the 2 commits that we want to remove. So we can revert our current branch to a previous commit, discarding completely the recent ones that will remain available on the unstable branch.

to see what's the commit that we want to revert to:

git log


we need to read the hashcode associated with the commit, to be able to perform our rollback(hard reset):

pantinor@pantinor gittest$ git reset --hard f331e52f41a862d727869b52e2e42787aa4cb57f
HEAD is now at f331e52 added new file


If you now execute a git status or a git log, you will see no trace of the unstable commit, that are instead accessible in the unstable branch.

On current:
 

pantinor@pantinor gittest$ cat test.txt 
text
pantinor@pantinor gittest$ git log
commit f331e52f41a862d727869b52e2e42787aa4cb57f
Author: Paolo Antinori <pantinor redhat.com="redhat.com">
Date:   Sun Dec 16 20:20:15 2012 +0000

    added new file


 On branch:

pantinor@pantinor gittest$ git checkout unstable 
Switched to branch 'unstable'
pantinor@pantinor gittest$ cat test.txt 
text
modification1
modification2
pantinor@pantinor gittest$ git log
commit 7005a92a3ceee37255dc7143239d55c7c3467551
Author: Paolo Antinori <pantinor redhat.com="redhat.com">
Date:   Sun Dec 16 21:05:48 2012 +0000

    second commit

commit 9ad2aa8fae1cbd844f34da2701e80d2c6e39320e
Author: Paolo Antinori <pantinor redhat.com="redhat.com">
Date:   Sun Dec 16 21:05:23 2012 +0000

    first commit

commit f331e52f41a862d727869b52e2e42787aa4cb57f
Author: Paolo Antinori <pantinor redhat.com="redhat.com">
Date:   Sun Dec 16 20:20:15 2012 +0000

    added new file


Friday, November 9, 2012

REST Invocation With Maven

Recently I had to invoke some REST service in one of my Maven builds.

I had never did it before but I was expecting to find some ready to use component that could allow me to do all the things that I needed directly from configuration but it wasn't the case.

I did the typical search to see what was available and I have found some good tip here and there.

But the conclusion is that there is not a ready "off the shelf" component.

The 2 most practical options seem to be:

- use an Ant GET Task
- embed Groovy code in you r script

Since the first option work only with the verb GET I decided to use the Groovy approach.

Let's say that we want to invoke a service via POST like this:

 
pantinor@pantinor maven_rest$
    curl -d appid=YahooDemo -d query=madonna -d \ 
    context="renaissance favored the Virgin Mary for inspiration" \ 
    http://search.yahooapis.com/ContentAnalysisService/V1/termExtraction


Produces this output:

virgin mary
renaissance
inspiration


An example taken from http://developer.yahoo.com/search/content/V1/termExtraction.html


This is one way to do that in Maven

Add some useful dependency

        
            org.codehaus.groovy.modules.http-builder
            http-builder
            0.5.1
        
 
Specify the Groovy plugin
   
    org.codehaus.groovy.maven
    gmaven-plugin
    1.0
    
     
      generate-resources
      
       execute


       ...


Add add the proper Groovy code

import groovyx.net.http.RESTClient
import groovy.util.slurpersupport.GPathResult
import static groovyx.net.http.ContentType.URLENC
import static groovyx.net.http.ContentType.XML

yahoo = new RESTClient('http://search.yahooapis.com/ContentAnalysisService/V1/termExtraction')

def response = yahoo.post(
    contentType: XML,
    requestContentType: URLENC,
    body: [appid:"YahooDemo", query:"madonna", context:"renaissance favored the Virgin Mary for inspiration"] 
)
log.info "yahoo response data: ${response.data}"

This is the full pom.xml file


 4.0.0
 test
 maven-rest
 1.0.0

 Maven Rest Example


            org.codehaus.groovy.modules.http-builder
            http-builder
            0.5.1


    org.codehaus.groovy.maven
    gmaven-plugin
    1.0
    
     
      generate-resources
      
       execute


        <![CDATA[
import groovyx.net.http.RESTClient
import groovy.util.slurpersupport.GPathResult
import static groovyx.net.http.ContentType.URLENC
import static groovyx.net.http.ContentType.XML

yahoo = new RESTClient('http://search.yahooapis.com/ContentAnalysisService/V1/termExtraction')

def response = yahoo.post(
    contentType: XML,
    requestContentType: URLENC,
    body: [appid:"YahooDemo", query:"madonna", context:"renaissance favored the Virgin Mary for inspiration"] 
)
log.info "yahoo response data: ${response.data}"
        ]]>


That will produce the following output:

pantinor@pantinor maven_rest$ 
    mvn install | grep -i "yahoo"
    [INFO]  yahoo response data: virgin maryrenaissanceinspiration